Ishan Shirode
Production AI Engineer
Bridging ML research with robust backend engineering. I architect and deploy scalable AI systems—from high-speed RAG pipelines to automated MLOps architectures.
About Me
I specialize in building production-grade AI systems using RAG, FastAPI, MLOps, and LLM orchestration.
My focus is moving AI solutions beyond notebooks and into scalable, deployable systems that drive real business value.
My Skills
Artificial Intelligence
Expertise & Tools
MLOps & Engineering
Data & Programming
Professional Skills
My work experience
AI/ML Intern — Blackhole Inverse | Oct 2025 – Present
• Engineered autonomous AI systems, task review agents, and automated workflow pipelines. • Built modular components including agent registries and plug-in abstraction layers. • Delivered 15+ production-level tasks and developed event-driven HR/ERP integrations.
SEO Intern — Elfoxis Digital | Apr 2025 – Jun 2025
• Architected automated reporting dashboards to track keyword performance and global traffic trends. • Executed data-driven SEO strategies that successfully optimized content ranking metrics. • Generated actionable analytics to drive executive decision-making and cross-functional alignment.
Engineering Activity
120+
Contributions
15
Repositories
Multi-LLM Council
High-Impact AI Solutions
AI-Powered Portfolio Platform
A full-stack RAG and Agentic LLM platform that transforms raw developer data into a recruiter-ready experience.
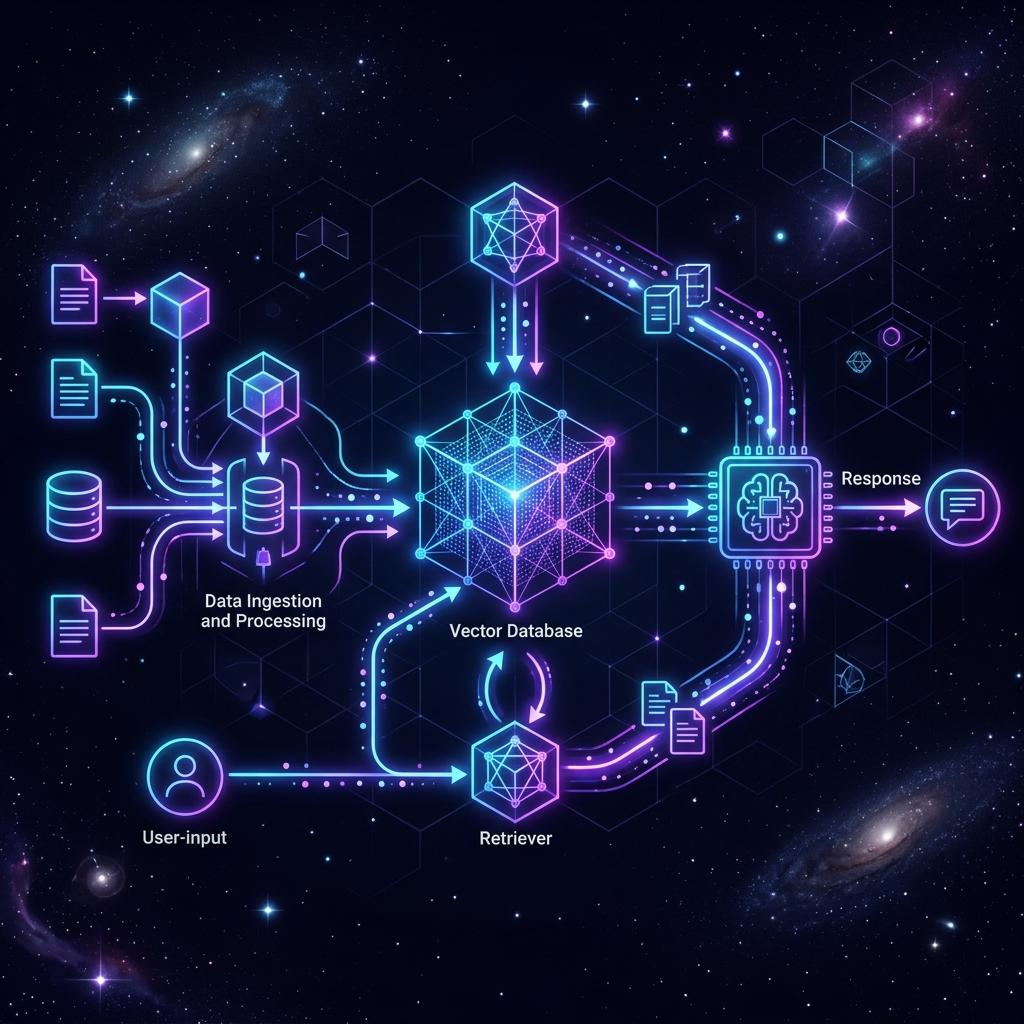
AI Knowledge Assistant (RAG Engine)
A production-grade Retrieval-Augmented Generation engine executing hybrid search across academic corpuses.
DriftGuard-ML
A closed-loop MLOps pipeline featuring automated drift detection, alerting, and Champion-Challenger retraining.
How I Build AI Systems
1. Enterprise RAG Pipeline
2. Automated MLOps (DriftGuard)
3. Multi-LLM Council
4. Scalable Inference API
My Education
My Certifications
Leadership & Activities
Anti-Ragging Head
Student Council
Joint Digital Head
AS&H Department